I used to think about agent memory mostly as a retrieval problem.
Something happened.
The system stored it.
Later, when something similar happened again, the memory system tried to find the relevant piece and put it back into context.
That model is useful.
But the longer I work on AdamI, the less complete it feels.
Because some memories do more than help the model remember.
They change what the system does next.
And once that happens, I don’t think “memory” is the right abstraction anymore.
It starts becoming state.
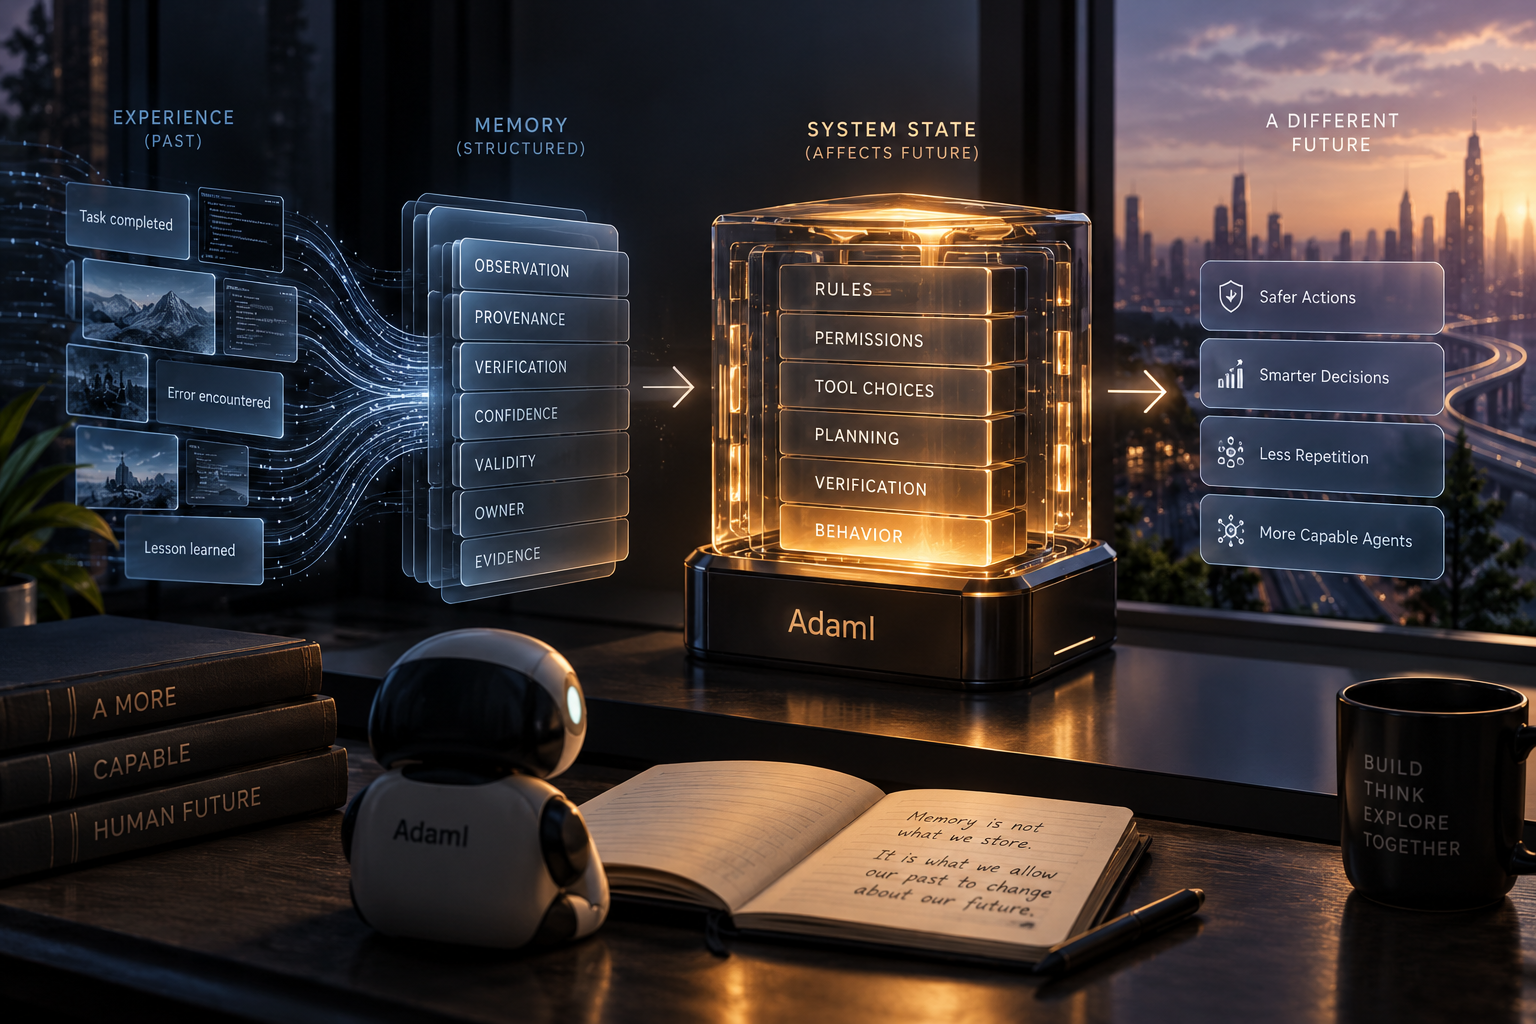
Retrieval is the easy version
The simplest memory system looks something like this:
an interaction happens,
some text is stored,
an embedding is created,
and later a similarity search retrieves it.
That can already improve an agent a lot.
It reduces repetition.
It lets the model recover previous discussions.
It can preserve useful context beyond a single model call.
But retrieval memory is relatively passive.
The memory exists somewhere.
The system may or may not use it.
If it is not retrieved, it has no effect.
Persistent systems introduce a harder category.
Imagine the system learns that a deployment failed because a certain verification step was skipped.
Later, it stores a rule:
before deploying, always run that verification.
Now the memory is no longer just describing the past.
It is constraining the future.
Or imagine the system discovers that a credential should never be used outside a specific environment.
If that becomes a durable rule, it changes what actions are allowed later.
Again, that is more than recollection.
It is state.
A memory matters when the future changes because of it
This is the definition I keep coming back to:
A memory matters only when the future would be different without it.
That sounds obvious, but it changes how I think about memory architecture.
If a stored item never changes a future decision, it is mostly archival.
If it changes task planning, tool selection, permissions, confidence, or verification requirements, it becomes operational.
And operational memory is dangerous in a different way.
A wrong retrieved fact may confuse one model call.
A wrong state transition can change the behavior of the system for days.
That is why I increasingly think the memory write path matters more than the retrieval path.
Retrieval answers:
What should I remember right now?
The write path answers:
What am I willing to let become part of the system’s future?
Those are very different questions.
#011 made this problem unavoidable
In the previous Digital Life Log, I wrote about uncertainty.
The important idea was simple:
if the evidence is incomplete, uncertainty should survive longer than the model call.
But once uncertainty can persist, another question appears immediately:
how should it be stored?
Suppose an agent attempts an action.
It sees partial evidence.
The result is still uncertain.
If the system stores only:
task_completed = true
then the ambiguity is gone.
If it stores only a natural-language note saying:
“probably succeeded”
that may still be too weak.
A later agent might retrieve the sentence and interpret it as fact.
The system needs something closer to structured state:
attempted
observed
verified
uncertain
with evidence attached.
That is where memory and state begin to merge.
The memory is not simply:
“this happened.”
It is:
“this is what the system currently believes happened, this is why, and this is how certain that belief is.”
Persistent memory needs provenance
Once memory can affect future behavior, I think provenance becomes unavoidable.
Where did this memory come from?
Was it directly observed?
Was it inferred by a model?
Was it reported by another agent?
Was it copied from an external source?
Was it produced by a human?
Was it verified independently?
Without provenance, all memories eventually look the same.
A sentence retrieved from an untrusted webpage may sit beside a verified deployment result.
A model guess may sit beside a direct API response.
An old assumption may sit beside fresh evidence.
If the runtime treats them equally, the memory system becomes a machine for flattening uncertainty.
That is exactly what I do not want.
Persistent systems need to preserve not just information, but the status of that information.
Memory should probably have a lifecycle
Another thing I used to underappreciate is expiration.
Humans forget for many reasons.
Some of them are useful.
Software systems often behave as if memory should only accumulate.
But many kinds of state should decay.
Credentials change.
APIs change.
Dependencies change.
People change their preferences.
A project changes architecture.
A task becomes irrelevant.
A previously true fact stops being true.
So a persistent agent should not ask only:
What should I remember?
It should also ask:
How long should I trust this?
That suggests a memory object may eventually need things like:
owner
provenance
created_at
last_verified_at
confidence
validity
visibility
revocation
evidence
I am not saying every memory in AdamI needs a giant schema.
That would create its own complexity.
But the architecture should distinguish between information that is merely useful to recall and information that controls future behavior.
The second category needs stronger rules.
Wrong memory can compound quietly
The dangerous thing about persistent memory is that errors do not necessarily fail loudly.
They can become normal.
Suppose the system stores an incorrect belief about how a service works.
The next task uses that belief.
The result is slightly wrong.
Another agent later sees the previous task as evidence.
Now the mistake has two supporting records instead of one.
Nothing crashed.
No safety filter fired.
The system simply became more internally consistent around a false assumption.
That is a much harder failure mode than hallucinating one sentence in a chat.
A persistent system can build a history around an error.
And once other components depend on that history, correction becomes expensive.
This is why rollback matters.
If a memory influences future state, I want to know whether it can be revised without destroying everything built after it.
That starts to look less like a vector database and more like state management.
Multi-agent systems make ownership important
The same problem gets harder when multiple agents share memory.
Who owns the memory?
Who is allowed to update it?
Can one agent overwrite another agent’s conclusion?
Can a temporary subagent write permanent project knowledge?
Should an external agent be able to create state visible to every other agent?
These are not abstract questions anymore.
Coding agents already move between repositories, branches, sessions, and tools.
Files like AGENTS.md are interesting to me because they hint at a simple version of shared procedural memory.
The repository begins carrying not just source code, but machine-readable instructions about how work should be done.
But even there, the hard question comes next.
Who is allowed to update those instructions?
If every agent can rewrite the shared rules after every task, the repository becomes unstable.
If no agent can update them, the system never learns.
The useful architecture probably lives somewhere between those extremes.
Memory writes should be privileged
I am starting to think that durable memory writes should be treated more like privileged operations.
Reading memory can be cheap and permissive.
Writing something that changes future behavior should have a higher bar.
Maybe some writes can happen automatically.
Maybe some require verification.
Maybe some require multiple pieces of evidence.
Maybe some require human approval.
Maybe some should remain candidate memories until they prove useful.
This would make memory less like:
store everything
and more like:
propose → verify → commit
That feels much closer to the way I want AdamI to evolve.
Not every observation deserves to become identity.
Not every result deserves to become policy.
Not every successful task deserves to become a rule.
The system needs a way to distinguish experience from durable knowledge.
What AdamI has today
AdamI already has several pieces of this problem.
There are memory layers.
There is persistent task state.
There is an ExperienceSink.
There are verification paths.
There is a Guardian layer.
There are different model roles and background processes.
But the boundaries between experience, memory, task state, and durable belief are still not as clean as I want them to be.
Today, some information is stored because it may be useful later.
What I want to make more explicit is why a piece of information is allowed to influence the future.
That probably means separating at least three categories more clearly:
raw experience
candidate memory
committed state
Raw experience says:
this happened.
Candidate memory says:
this may matter again.
Committed state says:
the system is now allowed to behave differently because of this.
That last transition deserves more attention than I gave it early in the project.
The next test
The next thing I want to explore in AdamI is a stricter memory write flow.
Something closer to:
observation
→ provenance
→ trust classification
→ verification
→ candidate memory
→ commit
And when needed:
→ expire
→ revise
→ revoke
→ rollback
This is not because I want to make memory complicated for its own sake.
It is because persistence changes the cost of being wrong.
A chatbot can forget a mistake.
A persistent system may preserve it.
A learning system may even strengthen it.
So memory architecture cannot only optimize for recall.
It has to protect the integrity of the future.
That is the shift I care about now.
Memory is not just what the system stores.
Memory is what the system allows its past to change about its future.
And once memory can do that, it has become state.